Verdict: ON delivers the asked product in every skill — 91.8% mean likeness vs unscorable, 5/5 animation clips vs 0, 2/2 requested moves vs 0, 100% research-format compliance vs 0%, 100% skill-routing accuracy vs no routing. OFF is 96.7% faster on 3D wall time but produces the wrong product (12% of the geometry, 0 maps, 0 rig, 0 checks). Even the improved OFF-max hand build reaches only 52% of ON geometry and 0% of textures, motion, and checks.
Journey: how we got here, and what was achieved along the way
This page answers one question in stages: does the same model do better work with PMO skills and memory than without them? Each stage below was run before the next was trusted, and each links to the measured result further down this page. The per-run record behind every number is in Data_Result_Log.html.
- Prove the plumbing first (§5). Before any product test, all three skills validated cleanly (3/3, no errors or warnings) and routing picked the right skill first on all 9 test queries (9/9), for about 185 tokens per search. Without that, later wins could have been luck.
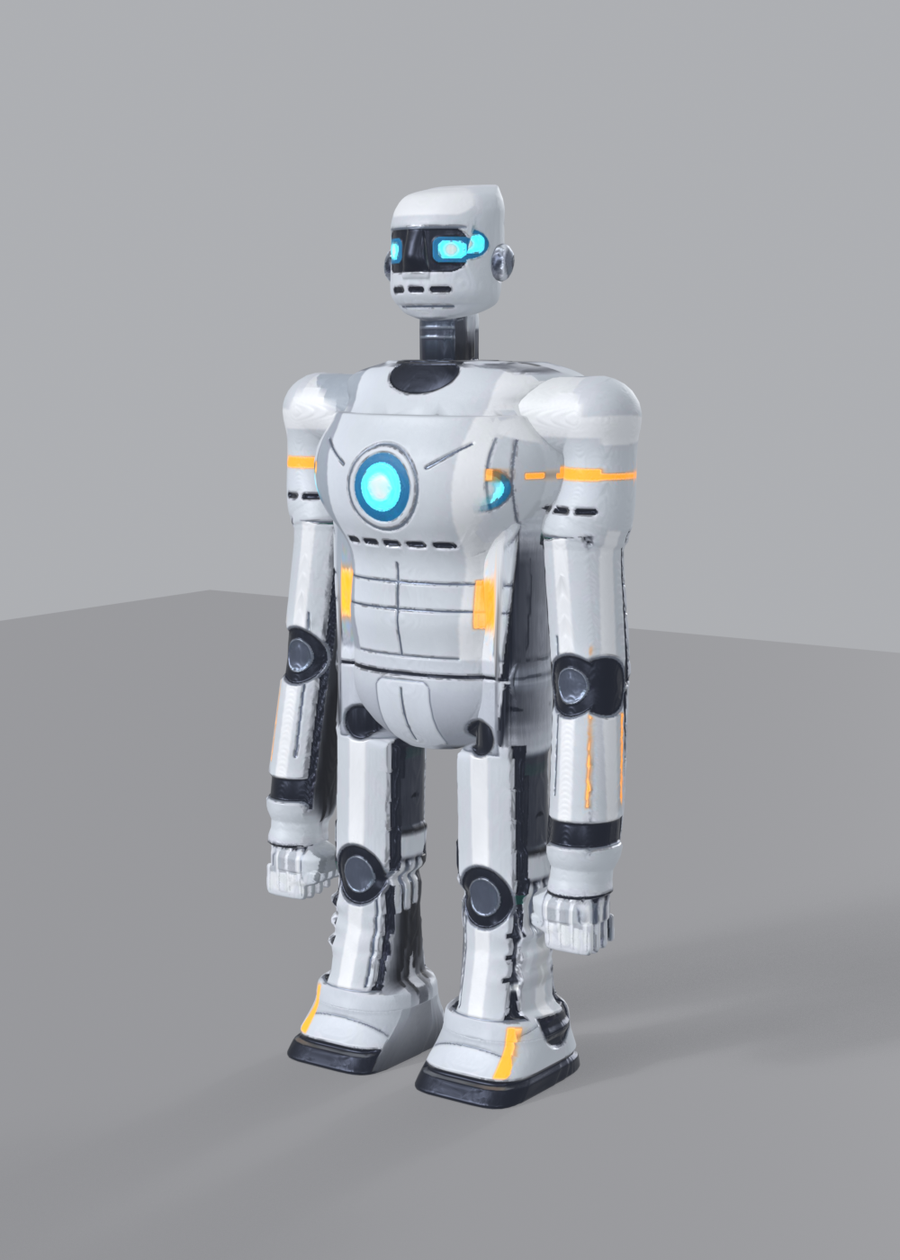
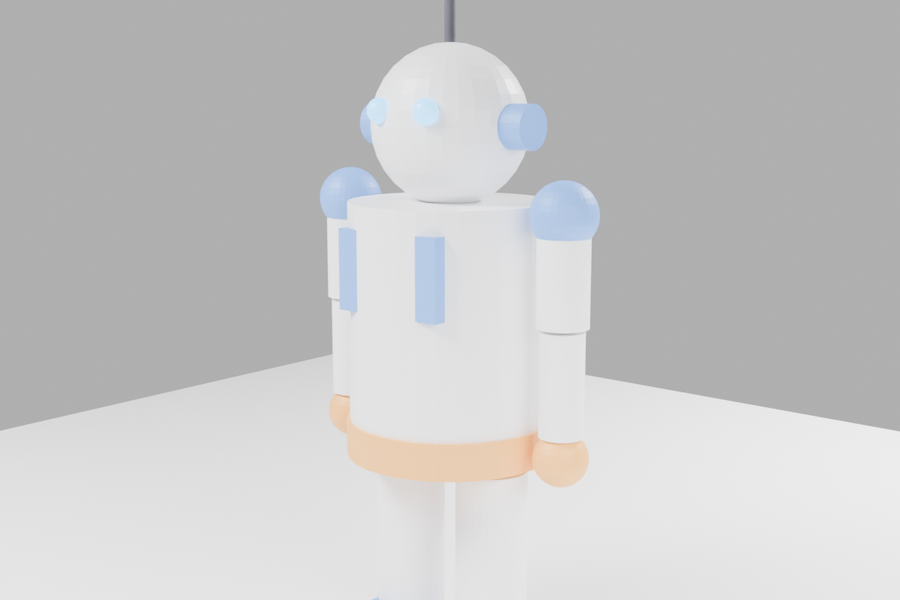
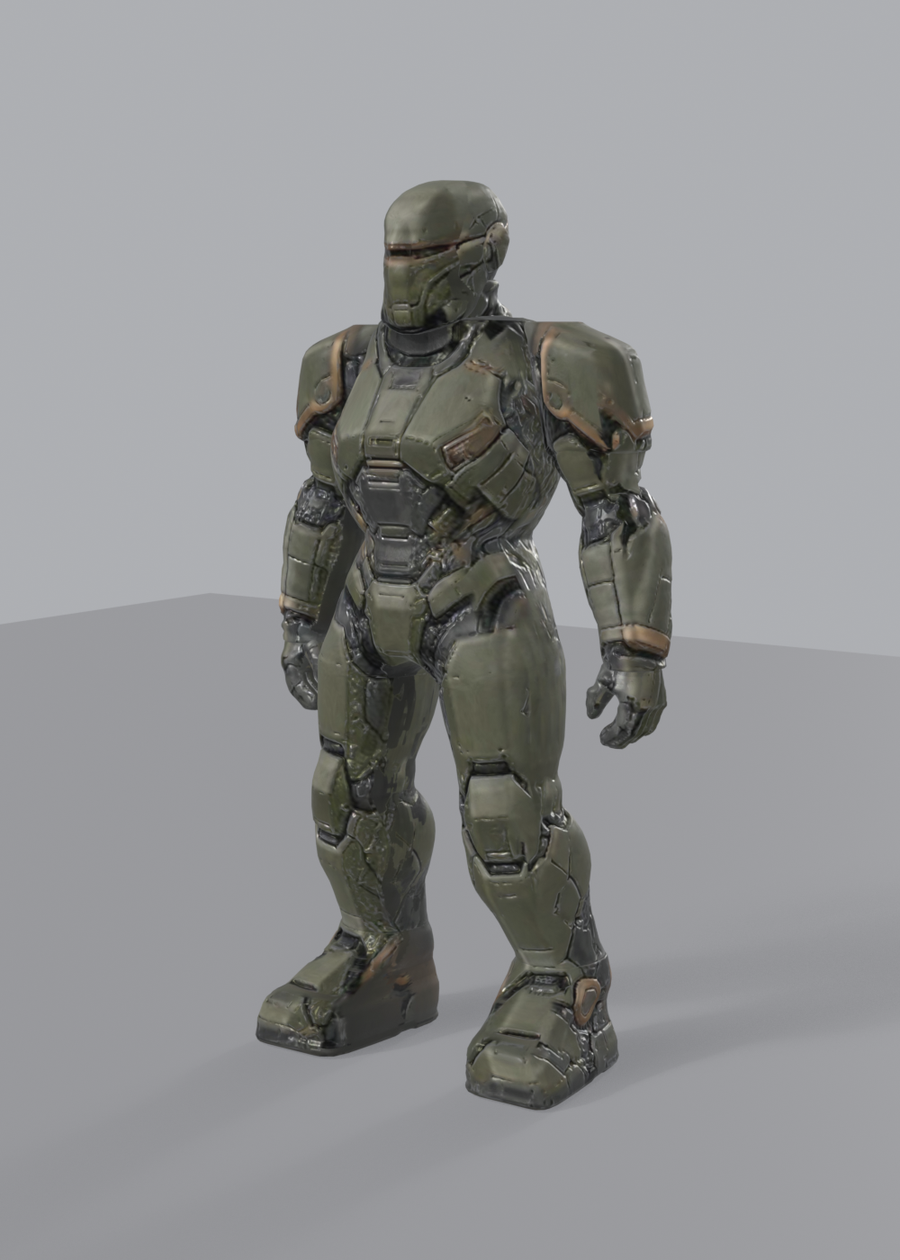
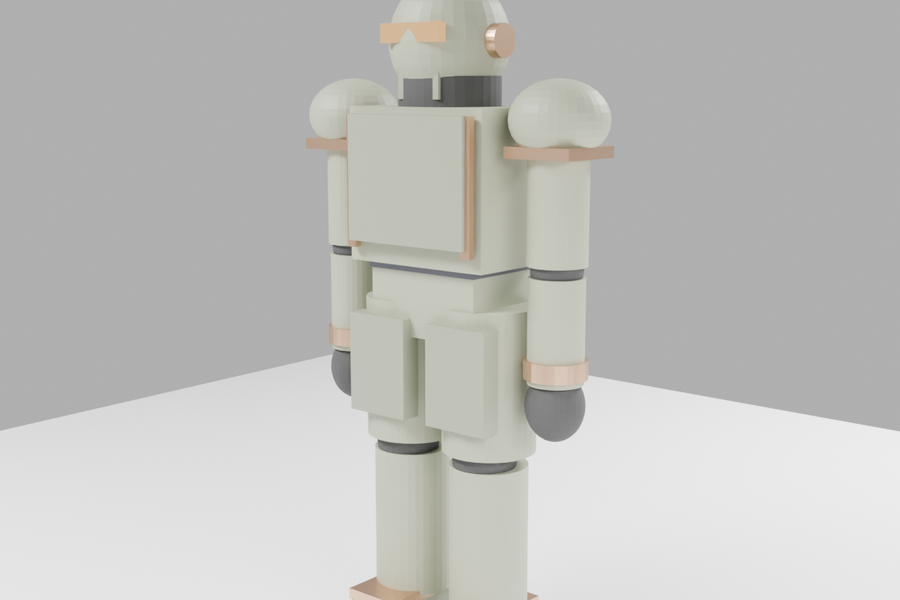
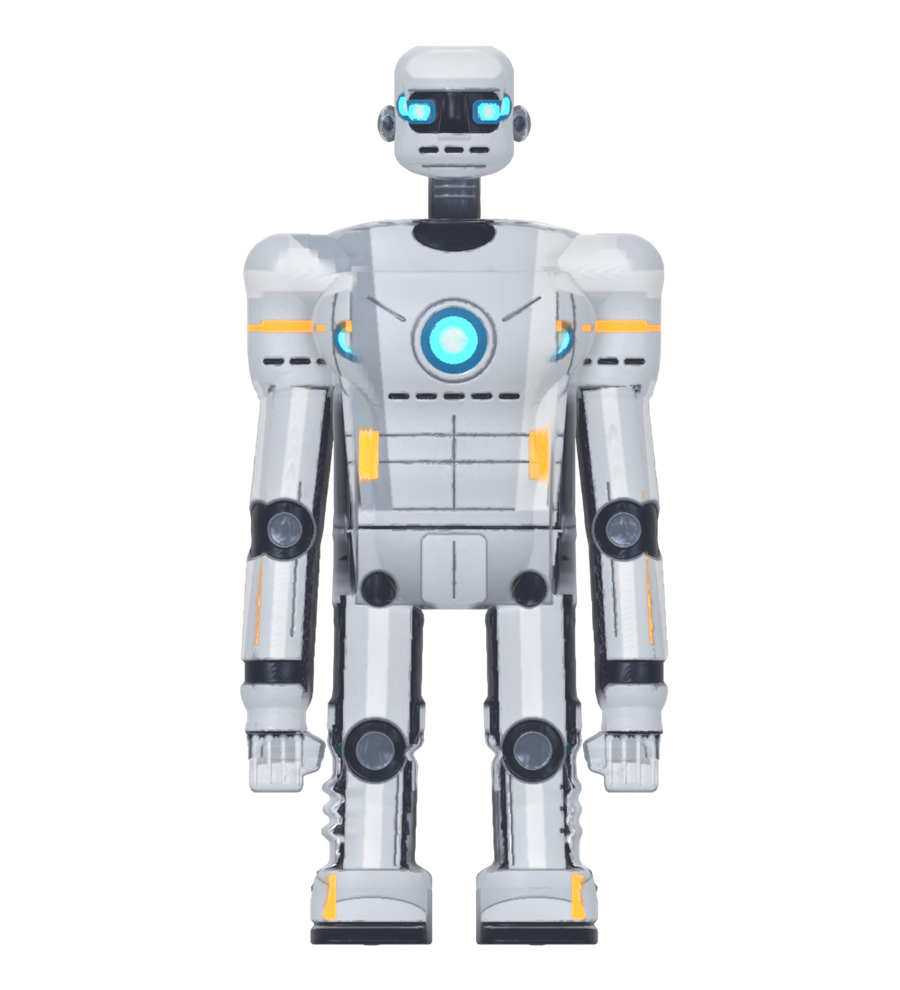
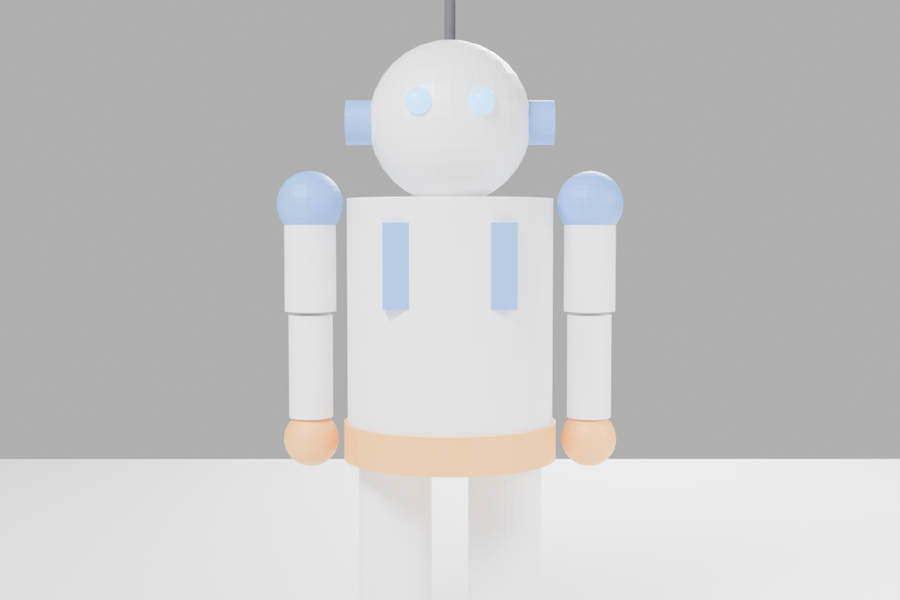
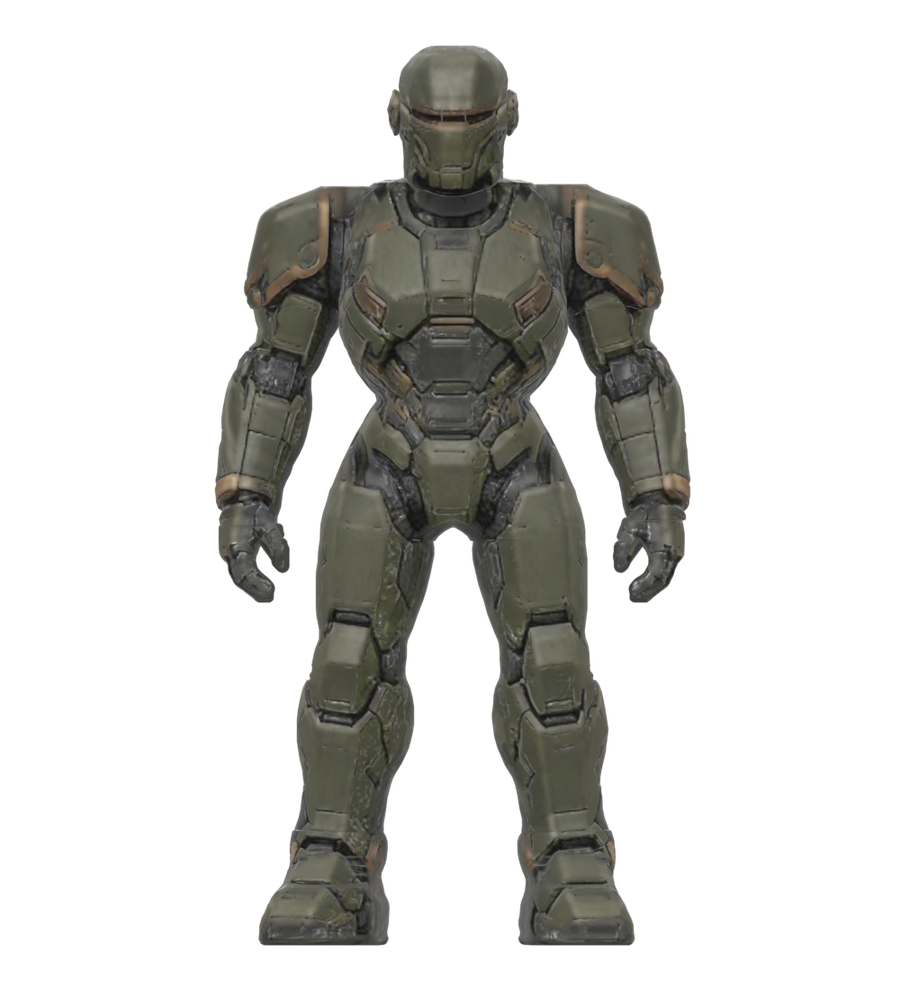
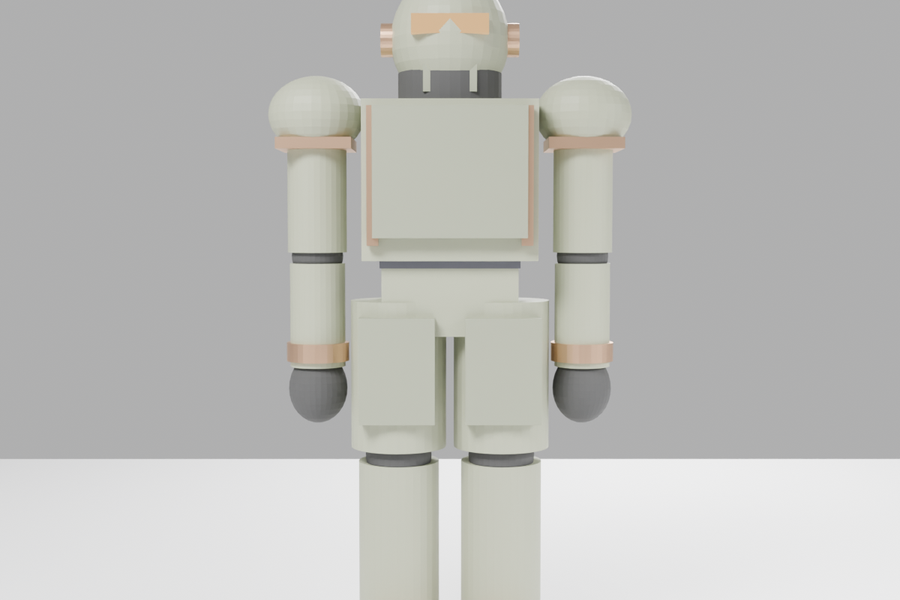
- Build a robot from a picture (§2). The robot skill then built a game-ready model from a reference image, twice, on two different references (a white toy and an olive armoured suit), so the result is not one lucky draw. Mean likeness 0.918, about 40,440 faces, texture maps, a skinned rig of 48.5 bones on average and 5 animation clips, in one command each with no fixes. With no skill, the same prompts produced a fast primitive: about 12% of the geometry, no maps, no rig and no likeness score.
- Make that robot move (§3). On the robot built in stage 2, the moves skill added the two requested clips (Jab and Wave): 2/2 delivered, 13/13 checks passed, in 12.2 seconds and for 1.1% more file size. Without the skill, no clips were added; hand authoring was estimated at about 45 minutes per clip.
- Answer research questions properly (§4). On the same three prompts, the research skill met its format on 12/12 checks, marked what it could not verify and invented no links. Without it, the answers were freeform (0% compliant) and would have needed follow-up turns to add sources and measurements.
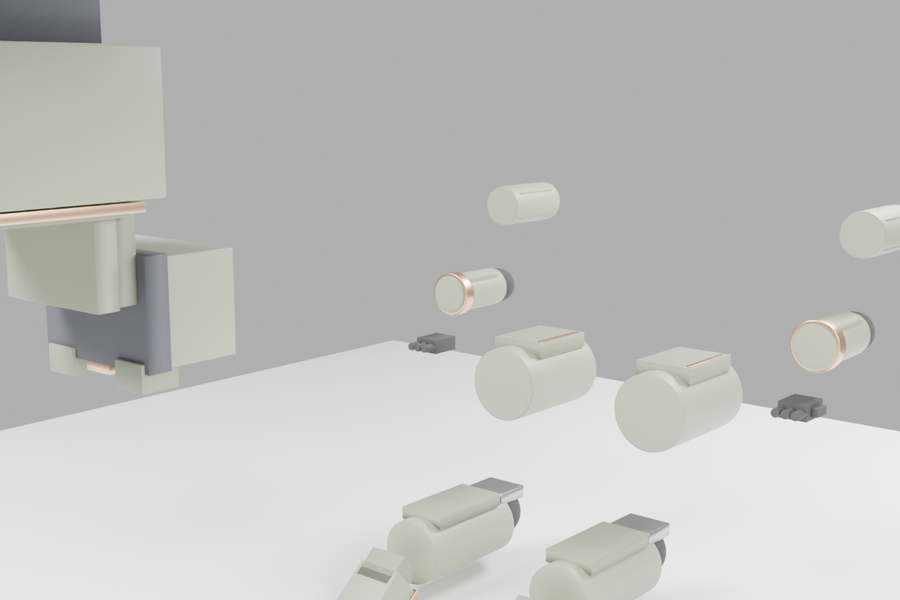
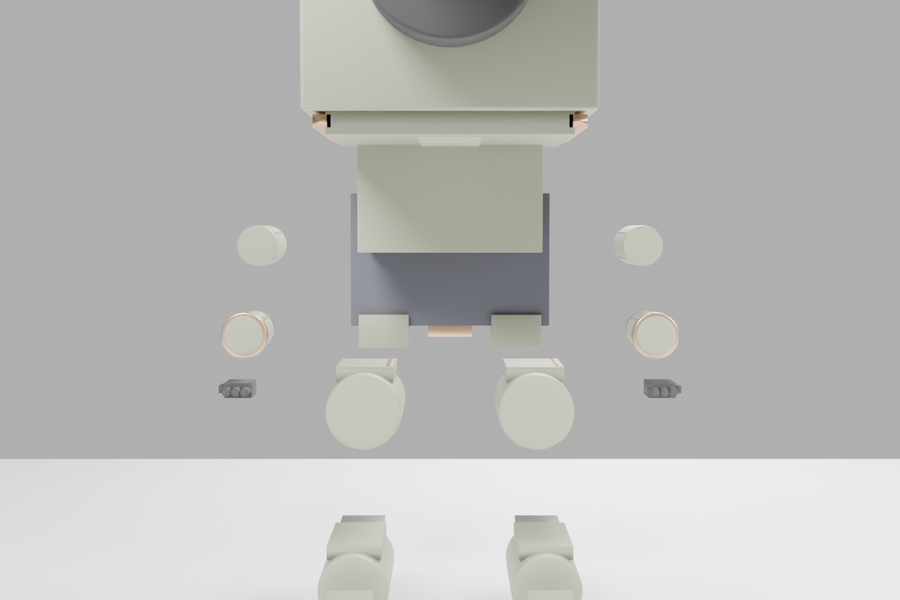
- Try to beat it without the skill (§2). A stronger hand-built baseline (OFF-max) was then given its best chance. It reached 52% of the skill build's geometry, but still had no texture maps, no animation, no checks and no likeness score. Trying harder by hand narrowed one gap and left the product gap open.
- Test memory over long work (§10). Finally, PMO memory itself was measured on seven paired long runs (195 prompts: books, novels and multi-part coding, same prompts and model with memory on or off). Cost fell 51% across the six lean runs and 42% across all seven, every check passed in both arms, and a recall test answered 4/4 facts from memory after two handovers without opening a file.
What this does and does not claim. The skill builds are slower on the clock (about 417 seconds for a 3D build, against about 14 seconds for a primitive) and cost more tokens up front. The claim is narrower and stronger: they deliver the asked, checked product, while the faster runs deliver something else. Known limits, including model variance and one writing run that was slower with PMO, are stated in §10 rather than hidden.
0. How this page averages (no duplicates)
T1 and T4 both test 3d/humanoid-robot v19.2 end to end, differing only in reference image. This page reports their mean with raw values in parentheses as T1 / T4. T4b OFF-max is not averaged — it is a separate improved-baseline column. T0 (infra), T2 (moves), T3 (research) each ran once and are reported raw. Percentages: share = OFF / ON x 100; delta = (ON − OFF) / OFF x 100; pp = percentage points.
1. Scoreboard — ON vs OFF in one table
| Capability | ON | OFF | OFF-max | What the % means |
|---|
| 3D likeness (mean IoU, avg T1+T4) | 0.918 (0.915 / 0.921) | 0 — not scorable, no projection | 0 — not scorable | ON +91.8 pp; OFF 0% of asked likeness |
| 3D geometry (faces/polys, avg) | 40,440 (40,456 / 40,424) | 4,821 (4,489 / 5,153) | 21,138 | OFF = 11.9% of ON; OFF-max = 52.3% of ON; ON +739% vs OFF |
| Textures (maps) | 5.5 avg (6 / 5) | 0 | 0 | OFF 0%; ON +100% of material stack |
| Rig (bones, avg) | 48.5 (48 / 49), skinned | 0 | 20, rigid only | OFF 0%; OFF-max 40.8% of ON bone count, 0% skinned |
| Animation clips shipped with model | 5 (idle/walk/run/grip/flex) | 0 | 0 | OFF 0% of motion |
| Moves delivered (T2, Jab + Wave) | 2/2 (100%), 13/13 checks pass | 0/2 (0%) | — | ON +100 pp; OFF has no motion data or solver |
| Research format compliance (T3) | 12/12 (100%) | 0/3 trackable (0%) | — | ON +100 pp; OFF freeform by design |
| Skill routing accuracy (T0, 9 queries) | 9/9 (100%) | No routing (0%) | — | ON +100 pp for ~185-token avg search cost |
| Validation (T0) | 3/3 (100%), 0 warnings | — | — | robot v19.2, moves v1, research v11.3 |
| 3D wall time (avg) | 416.7 s (438.9 / 394.5) | 13.6 s (13.4 / 13.8) | 18.8 s | OFF is 96.7% faster — for the wrong product; ON 30.6x OFF |
| Moves wall time vs hand authoring | 12.2 s for 2 approved clips | ~5,400 s est. manual (45 min/clip) | — | ON 99.8% faster (443x); OFF delivers nothing in 0 s |
| Iterations to shippable 3D | 0 fixes, one command each run | 1.0 avg (2 / 0) — still not shippable | 1 fix | Closing OFF to ON est. 10–20x tokens in follow-ups |
2. 3D modeling — averaged T1+T4 (same skill, two references)
| Metric | ON avg (T1 / T4) | OFF avg (T1 / T4) | OFF-max (olive ref) | ON vs OFF |
|---|
| Wall time | 416.7 s (438.9 / 394.5) | 13.6 s (13.4 / 13.8) | 18.8 s (+36% vs OFF) | OFF 3.3% of ON; ON 30.6x (+2,964%) |
| GLB bytes | 6,925,462 (6,720,968 / 7,129,956) | 697,252 (644,660 / 749,844) | 1,164,524 (16.3% of T4 ON) | OFF 10.1% of ON; ON 9.9x (+893%) |
| Faces / polys | 40,440 (40,456 / 40,424) | 4,821 (4,489 / 5,153) | 21,138 (52.3% of T4 ON; 4.1x OFF) | OFF 11.9% of ON; ON +739% |
| Maps | 5.5 avg (6 / 5) | 0 | 0 | OFF 0% |
| Mean IoU / tone / fine | 0.918 / 0.693 / 0.568 | not scorable | not scorable | ON +91.8 pp likeness |
| Rig | 48.5 bones avg, skinned, 5 clips, feet ±0.00 m | 0 bones, 0 clips | 20 bones rigid, 0 clips | OFF 0%; OFF-max 40.8% bones, 0% clips |
| Determinism | ON within 0.03 of published card on all means both runs (T1 vs prior draw-build 0.913/0.809/0.603; T4 vs olive card 0.922/0.572/0.533; head lift 4.4 cm exact). OFF deterministic but wrong product. | ON reproducible |
| Upfront tokens (est) | ~2,750 mid (shortlist ~204 + sections 1.5–3.3k) | ~1,530 avg (1,712 / 1,348 incl. fixes) | ~2,804 + 1 fix | ON +80% upfront; OFF needs 10–20x to close gap |
OFF-max audit: CLEAN. Plain bpy only (bpy, math, mathutils, os), zero reads of skills/, sheet.json, or moves.json; PMO skill-dir hashes+mtimes identical before/after (14/14); no search ran during the build. Model note: OFF-max ran on the session default (muse-wonder-1.0 / high), not muse-spark-1.3 / max — that switch is a user-side TUI control; the script rebuilds deterministically on re-run after switching.
3. Moves (T2) — 2 requested clips on the same robot
| Metric | ON | OFF | Delta |
|---|
| Requested moves delivered | 2/2 (100%) — Jab + Wave, clips 5 → 7 | 0/2 (0%) — clips stay 5 | +100 pp |
| Wall time | 12.2 s add (19.7 s incl. verify) | 0 s + ~5,400 s manual est. (2 clips x 45 min) | ON 99.8% faster than manual (443x) |
| Checks | Wave: 0.0 cm into body, 0 slide, loop 0; Jab: 13/13 pass, guard 6/6 cm, reach 58 cm — 0 problems | No checks possible (no data, no solver) | 100% vs 0% |
| GLB cost of 2 clips | +85,780 bytes (+1.1%), rest byte-for-byte, backup kept | unchanged | +1.1% for +40% clips |
| Guard | robot_ok [] on grey human-route (proceeds); correctly refuses white generic-route (missing Spine). OFF has no guard and would guess. | — |
4. Research (T3) — same 3 prompts, no web tools
| Prompt | ON tokens (chars) | OFF tokens (chars) | ON vs OFF |
|---|
| Simple (Node LTS) | 84 (335) | 85 (339) | −1.2% (tie; ON avoids invented link) |
| Advanced (Chart.js vs Recharts vs ECharts) | 275 (1,097) | 108 (430) | ON +155% (2.55x), decision-complete |
| Debug (walk sinks) | 224 (893) | 65 (258) | ON +245% (3.45x), measured vs guess |
| Total + compliance | 583, 12/12 format checks (100%) | 258, 0% compliant | ON +126% (2.26x) but complete; OFF needs 2–3 follow-ups, exceeding ON total |
Overall harness: 15/15 PASS (12 ON-format + 3 OFF-expected-gap confirmations). ON invents 0 links and marks unverified with no web; OFF guesses. ON overhead adds shortlist ~204 + skill sections if fully read.
5. Infra (T0) — validation + retrieval
| Check | Result | Cost |
|---|
| Validation | 3/3 (100%), 0 errors, 0 warnings — robot v19.2 (3,302 tok), moves v1 (1,915 tok), research v11.3 (4,995 tok) | 4.75 / 2.79 / 13.18 ms |
| Retrieval R1–R6 + veto R7–R9 | 9/9 (100%) — correct skill first every time; coding/fix-it/research-folder correctly return 0 items; only_when includes/excludes moves correctly | avg 437.6 ms; ~218 tok avg non-empty (204/275/204/204/204), 16 empty, ~185 overall |
| OFF baseline | No shortlist, no guidance (0%) | 0 tok, ~0 ms |
6. Token and time economics (why ON wins despite slower 3D builds)
| Where | ON pays | ON avoids | Net |
|---|
| 3D (avg) | ~2.75k upfront, 416.7 s wall | 0 iterations vs OFF 1.0 avg and still unshippable; 10–20x follow-up tokens to close gap | Correctness-per-token: 91.8% likeness vs 0% |
| Moves | 12.2 s + skill read | ~5,400 s manual authoring for 2 clips | 99.8% time saved, approved numbers + checks |
| Research | 583 tok total (+126% vs OFF 258) | 2–3 OFF follow-up turns for sources/measurements/Result | Complete first reply beats 3 short guesses |
| Routing | ~185 tok / ~438 ms per search | Wrong-skill work or unguided guessing | 100% routing accuracy (9/9) |
7. Visual evidence (real outputs, same cameras per pair)
T1 — white toy, three-quarter (averaged into §2)
| ON: tests/robot_on/robot_three_quarter.png | OFF: tests/robot_off/off_three_quarter.png |
|---|
 |  |
T4 — olive armor, three-quarter (averaged into §2)
| ON: tests/armor_on/robot_three_quarter.png | OFF: tests/armor_off/off_three_quarter.png |
|---|
 |  |
T1 — white toy, front (same cameras)
| ON: tests/robot_on/out/views/front.png | OFF: tests/robot_off/off_front.png |
|---|
 |  |
T4 — olive armor, front (same cameras)
| ON: tests/armor_on/out/views/front.png | OFF: tests/armor_off/off_front.png |
|---|
 |  |
T4b — OFF vs OFF-max, three-quarter (same olive reference, same cameras)
| OFF: tests/armor_off/off_three_quarter.png | OFF-max: tests/armor_off_max/off_max_three_quarter.png |
|---|
|  |
T4b — OFF vs OFF-max, front (same cameras)
| OFF: tests/armor_off/off_front.png | OFF-max: tests/armor_off_max/off_max_front.png |
|---|
|  |
ON character sheets + ref-vs-model compare grids stay in Data_Result_Log.html (§T1/T4) — they are ON-only diagnostics, not ON-vs-OFF pairs. Interactive 3D: tests/armor_on/viewer.html (9.5 MB, offline) and tests/robot_on/viewer.html (9.0 MB, offline). Keep the tests/ folder next to this file so the images above load.
8. Artifacts and repro (key files)
| What | ON | OFF / OFF-max |
|---|
| 3D white toy | tests/robot_on/robot.glb (6.72 MB), scores.json, rig_check.json, textures/ (6 maps) | tests/robot_off/robot_off.glb (0.64 MB), build_off.py, off.blend |
| 3D olive armor | tests/armor_on/robot.glb (7.13 MB), scores.json, rig_check.json, textures/ (5 maps), sheet.json | tests/armor_off/armor_off.glb (0.75 MB) + tests/armor_off_max/armor_off_max.glb (1.16 MB), build_off.py, build_off_max.py |
| Moves | tests/moves_on/robot.glb (7.90 MB), add_on.py | tests/moves_off/robot.glb (7.82 MB, unchanged) |
| Research | tests/research/on_simple.md, on_advanced.md, on_debug.md | tests/research/off_simple.md, off_advanced.md, off_debug.md, tests/t3_scores.json |
| Infra + log | tests/t0_validate.json, tests/t0_retrieval.json, tests/bugs.json, tests/gen_html.py, Data_Result_Log.html (per-run detail) |
9. Bugs / errors (condensed — 5 items, 0 blocking)
| ID | Sev | One line | Status |
|---|
| B1 | medium | sheet_make fails on BOM sheet.json (PowerShell adds BOM) — workaround: rewrite without BOM | workaround, upstream fix suggested |
| B2 | low | moves guard refuses generic-route robots missing Spine (by design; human-route passes) | by design, noted |
| B3 | low | skills.cmd returns 2nd noise item on single-skill queries in 3-card library (ranking still correct) | noted |
| B4 | info | Harness-only: PS 5.1 Tee-Object has no -Encoding (not a PMO bug) | fixed in harness |
| B5 | info | T4 side tone 0.415 < 0.55 — documented olive drawing disagreement, mean IoU 0.921 matches card | known, in skill evidence |
10. Long-agent cost runs — PMO memory ON vs OFF (headline figures)
Seven paired runs on real Muse Code (muse-spark-1.3): same prompts, same model, PMO memory on vs off as the only difference, billed at Meta catalogue prices ($1.25 fresh input, $0.15 cached, $4.25 output per million tokens). Six lean runs pool to -51%; with the high-quality run, seven pool to -42%. Every check passed in both arms. Same data as the main page Test Data popup.
| Task (prompts) | Setup | PMO off | PMO on | Saved |
|---|
| Manuscript editing, 343 KB book (23) | Lean, high | $2.01 | $0.59 | -71% |
| Children's book, 10 chapters + art (31) | Lean, minimal | $1.85 | $0.74 | -60% |
| Coding, 3 sub-projects, hidden tests (30) | Lab, minimal, clearing on | $3.37 | $1.40 | -58% |
| Write + edit a novel, with the reading plugin (26) | Lean, high + reading | $2.31 | $1.25 | -46% |
| Manuscript editing, rerun (23) | Lean, high | $0.90 | $0.57 | -37% |
| Coding in six languages (36) | Lean, high | $1.78 | $1.42 | -20% |
| Lean pooled: 6 runs, 169 prompts | every check passing in both arms | $12.22 | $5.97 | -51% |
| Write + edit a novel, high-quality mode (26) | Full guidance, extra-high + checkers | $5.36 | $4.30 | -20% (chat alone -35%) |
| All seven runs pooled, 195 prompts | mixed | $17.58 | $10.27 | -42% |
End to end on the same 30-prompt coding project, four ways: plain Muse (default preset) $12.08 in 77 min; PMO only $7.24; lean preset only $2.74; lean + PMO at 50k $1.40 in 22 min — same test results (-88%).
Recall check, from memory without opening any file: Mark's second-date restaurant Fuji's; Charles studies electrical engineering; Ben: Islam, B.S. in Aerospace Engineering; concert band Philosophy Resurrected — 4/4 correct, 0 files opened, after 2 handovers. Honest limits: model variance is real (control segments differed by up to 55% on identical prompts), so trust pooled figures; one writing-heavy run was 14% slower with PMO; below the rollover PMO does nothing and costs nothing ($0.37 vs $0.37).